Jike Zhong

I am a third-year PhD student at the University of Southern California (USC). I work primarily with Prof. Konstantinos Psounis (he is fantastic!). My recent research focuses on LLM/VLM Post-Training (Reinforcement Learning, Distillation) and Evaluation, Reasoning & Agentic AI. I’m always open to discussion, collaboration, and mentorship!

Before my PhD, I completed my Bachelor's with double majors in CS and Statistics at Ohio State University from 2019-2022, working with great Prof. Wei-Lun Chao and Dr. Hong-You Chen. I have also spent some wonderful time at CCVL lab at Johns Hopkins University, supervised by Bloomberg Distinguished Prof. Alan Yuille.

I'm currently looking for Spring 2027 and Summer 2027 research internship opportunities, please feel free to reach out at jikezhon@usc.edu if you see a fit.

Jike Zhong standing in the ocean surf

What’s New

Selected Research

Full list of publications can be found on my Google Scholar page.

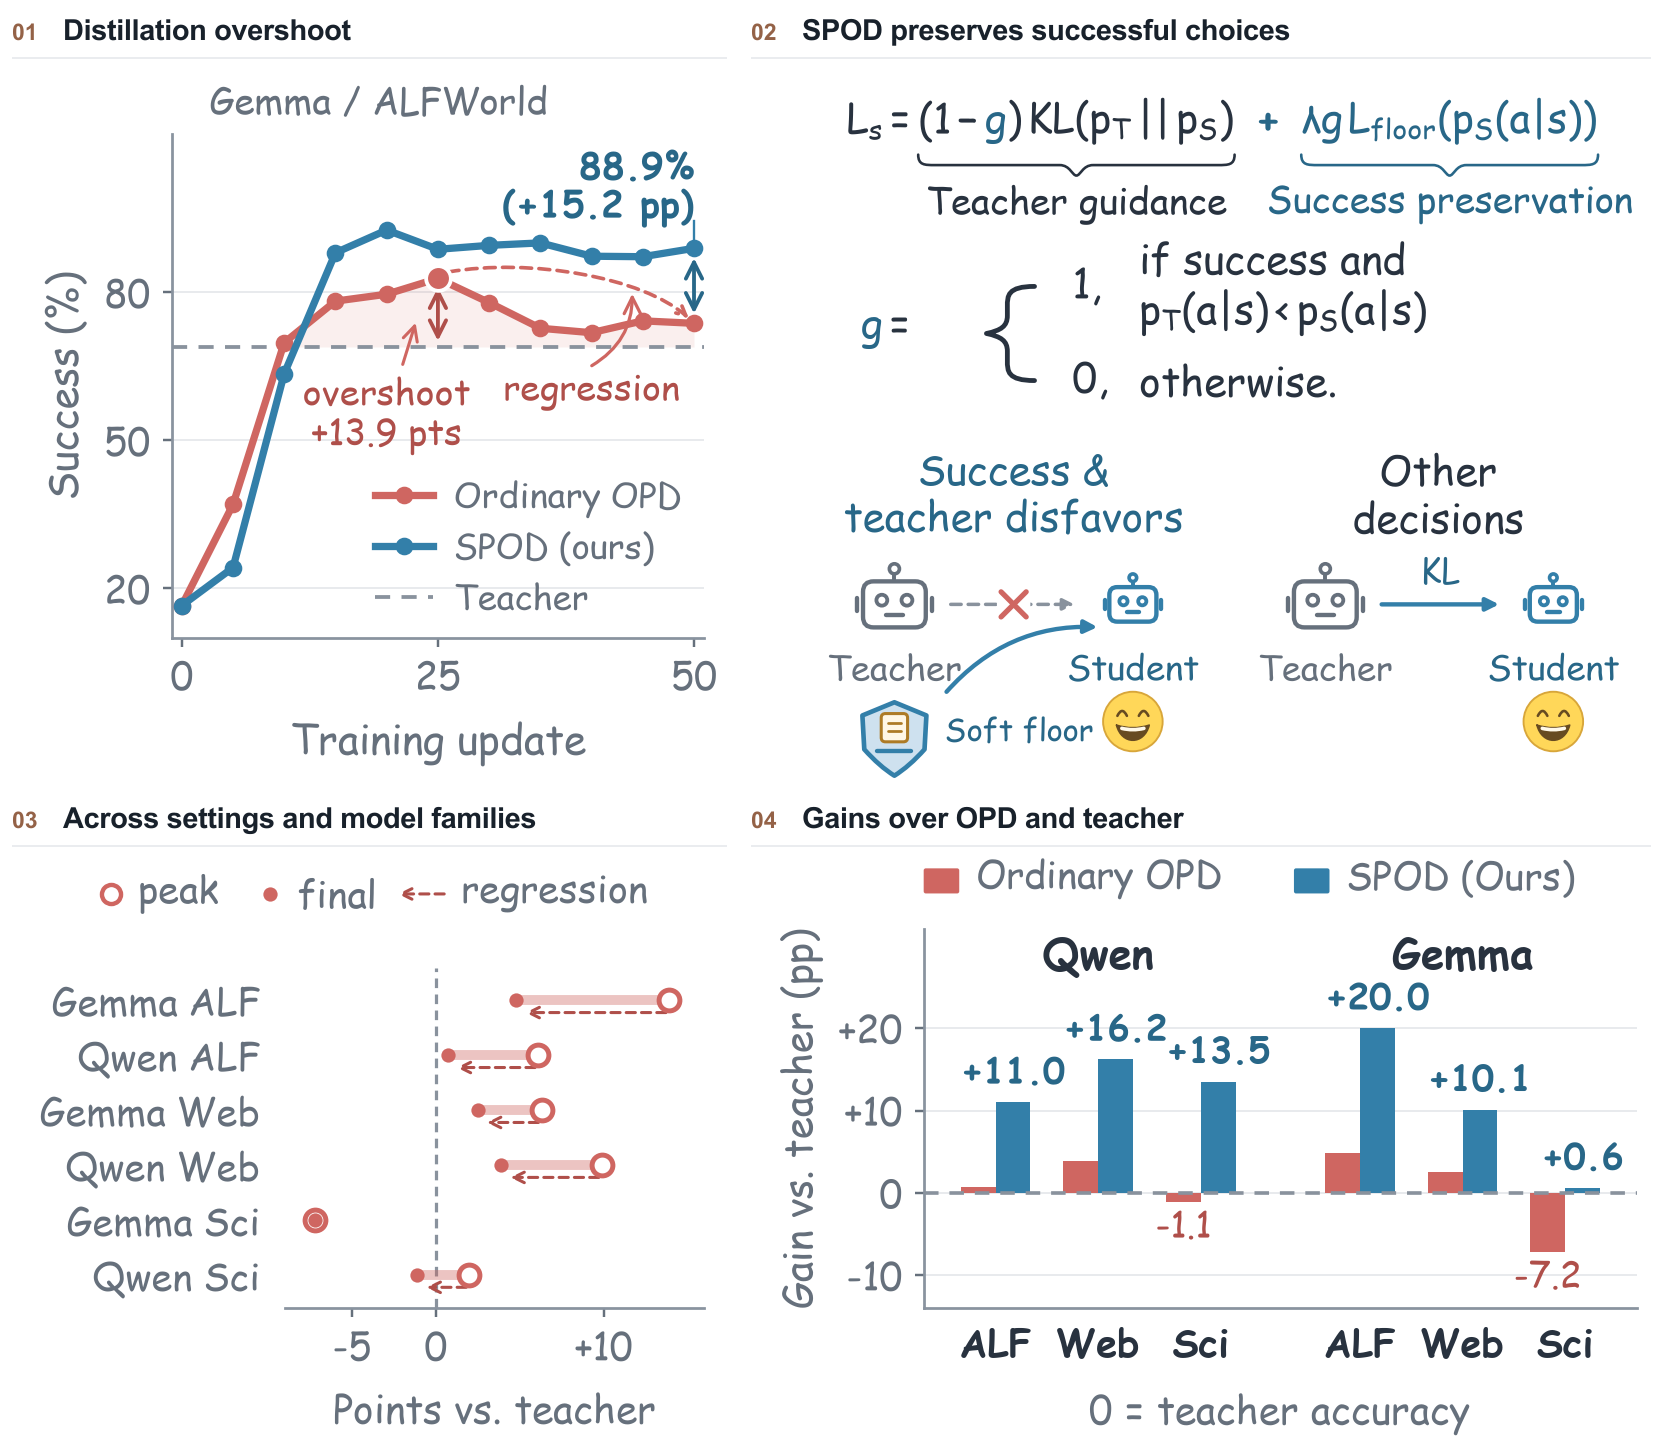
Panels A and C: distillation overshoot and regression across settings, SPOD's success-preserving objective, and final gains over the teacher.

Post-Training | OPDBeyond the Teacher: Understanding and Preserving Distillation Overshoot in Agentic On-Policy Distillation

Jike Zhong, Ming Li, Yuxiang Lai, Xi Xiao, Sheng Zhang, Ritwick Chaudhry, Tianle Chen, Jingyu Xie, Zheda Mai, Shao-Yuan Lo, Konstantinos Psounis, Yuanyuan Lei

arXiv preprint, 2026

We identify why student agents surpass their teachers during distillation, then lose those gains. Our success-preserving method, SPOD, improves final success by up to 15.2 percentage points over standard OPD and 20 points over the teacher.
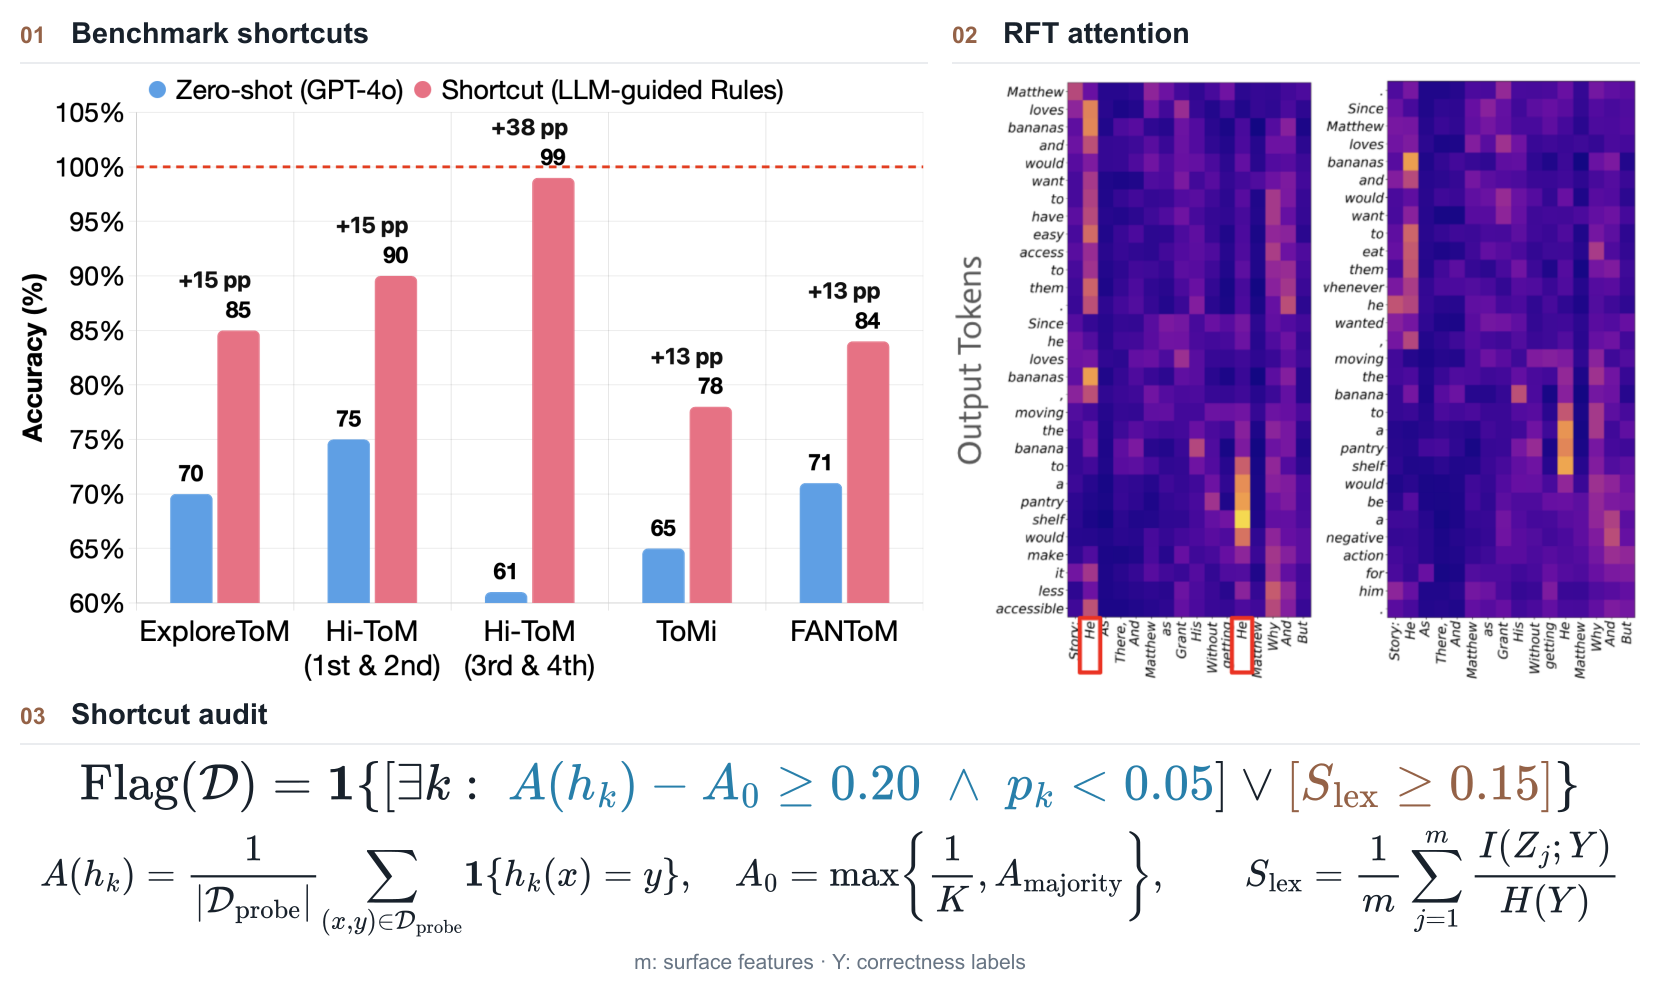
Theory of Mind shortcut benchmark results beside RFT attention heatmaps, with the paper’s rule-based and lexical shortcut-auditing criteria below.

Post-Training | RL | Shortcut LearningFrom Shortcuts to Reasoning: Robust Post-Training of Theory of Mind with Reinforcement Learning

Jike Zhong, Yuxiang Lai, Ming Li, Yuheng Li, Wuao Liu, Behzad Dariush, Konstantinos Psounis, Shao-Yuan Lo

ICML 2026

We expose shortcuts that inflate apparent theory-of-mind reasoning performance. On shortcut-resistant datasets, reinforcement fine-tuning with explicit reasoning improves generalization, higher-order reasoning, and robustness to counterfactuals.

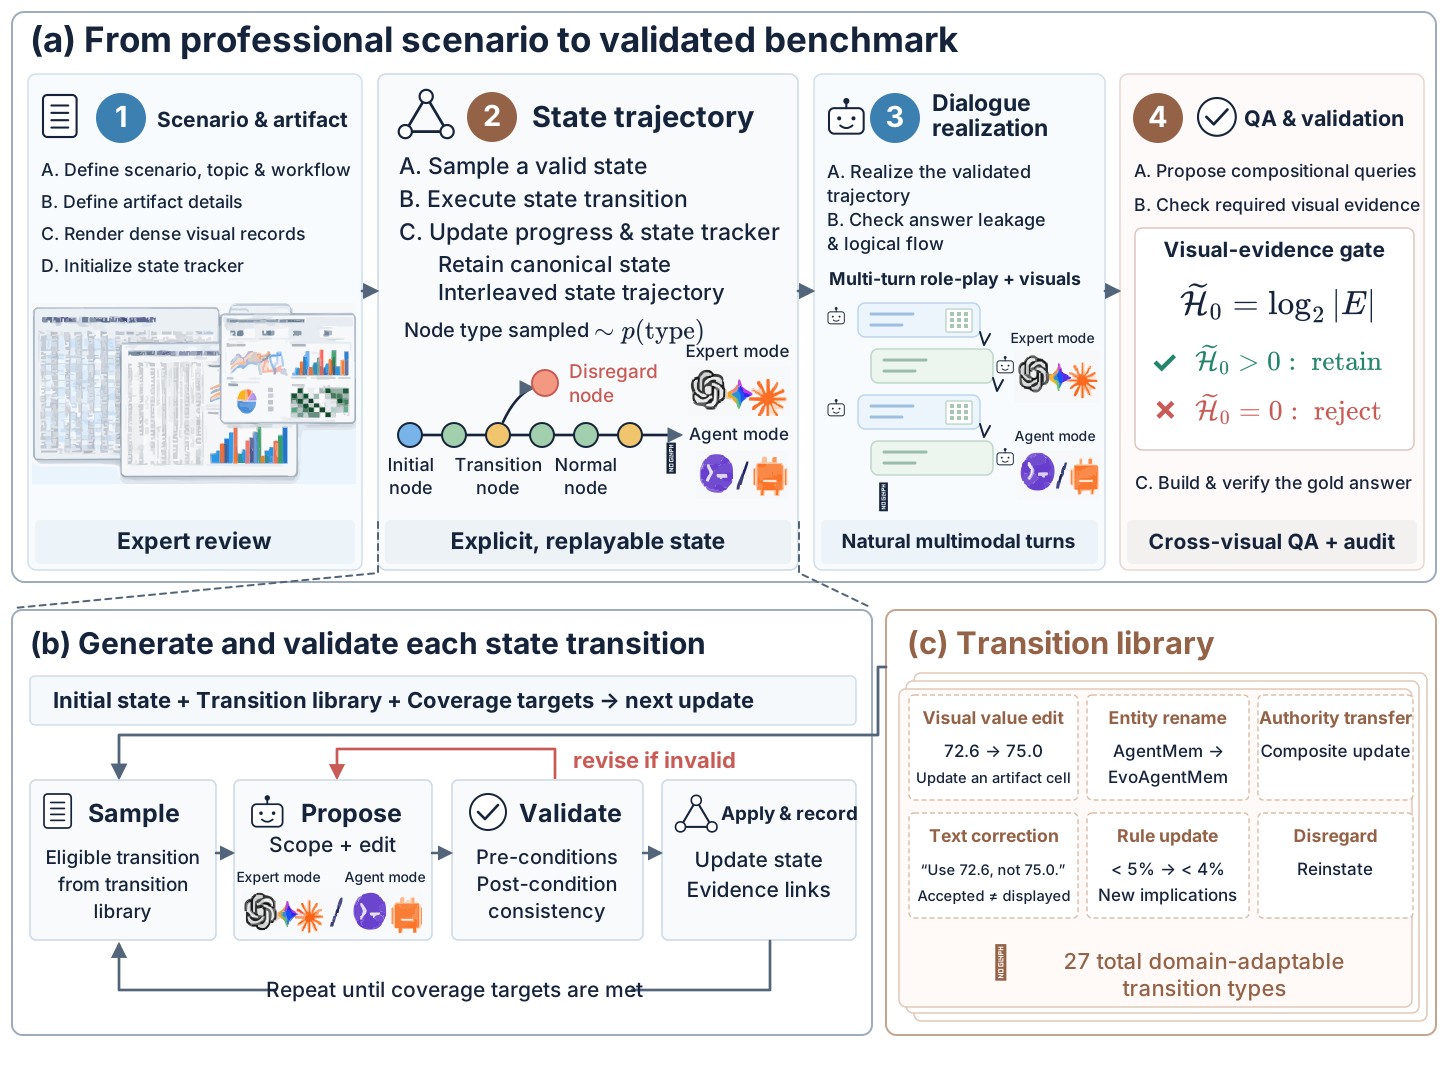
DSV-Mem construction pipeline emphasizing the state trajectory, the state-transition generation loop, and the transition library.

Agentic AI | Memory | EvaluationDSV-Mem: Evaluating Multimodal Memory in Professional Workflows for MLLM Agents

Jike Zhong, Ritwick Chaudhry, Xuanbai Chen, Tianchen Zhao, Linghan Xu, Yifan Xing, Nishant Sankaran

arXiv preprint, 2026

We benchmark how multimodal agents track and reconcile evolving, information-dense visual artifacts across professional workflows. DSV-Mem exposes state reconstruction as a key memory bottleneck and shows the value of explicit state tracking.

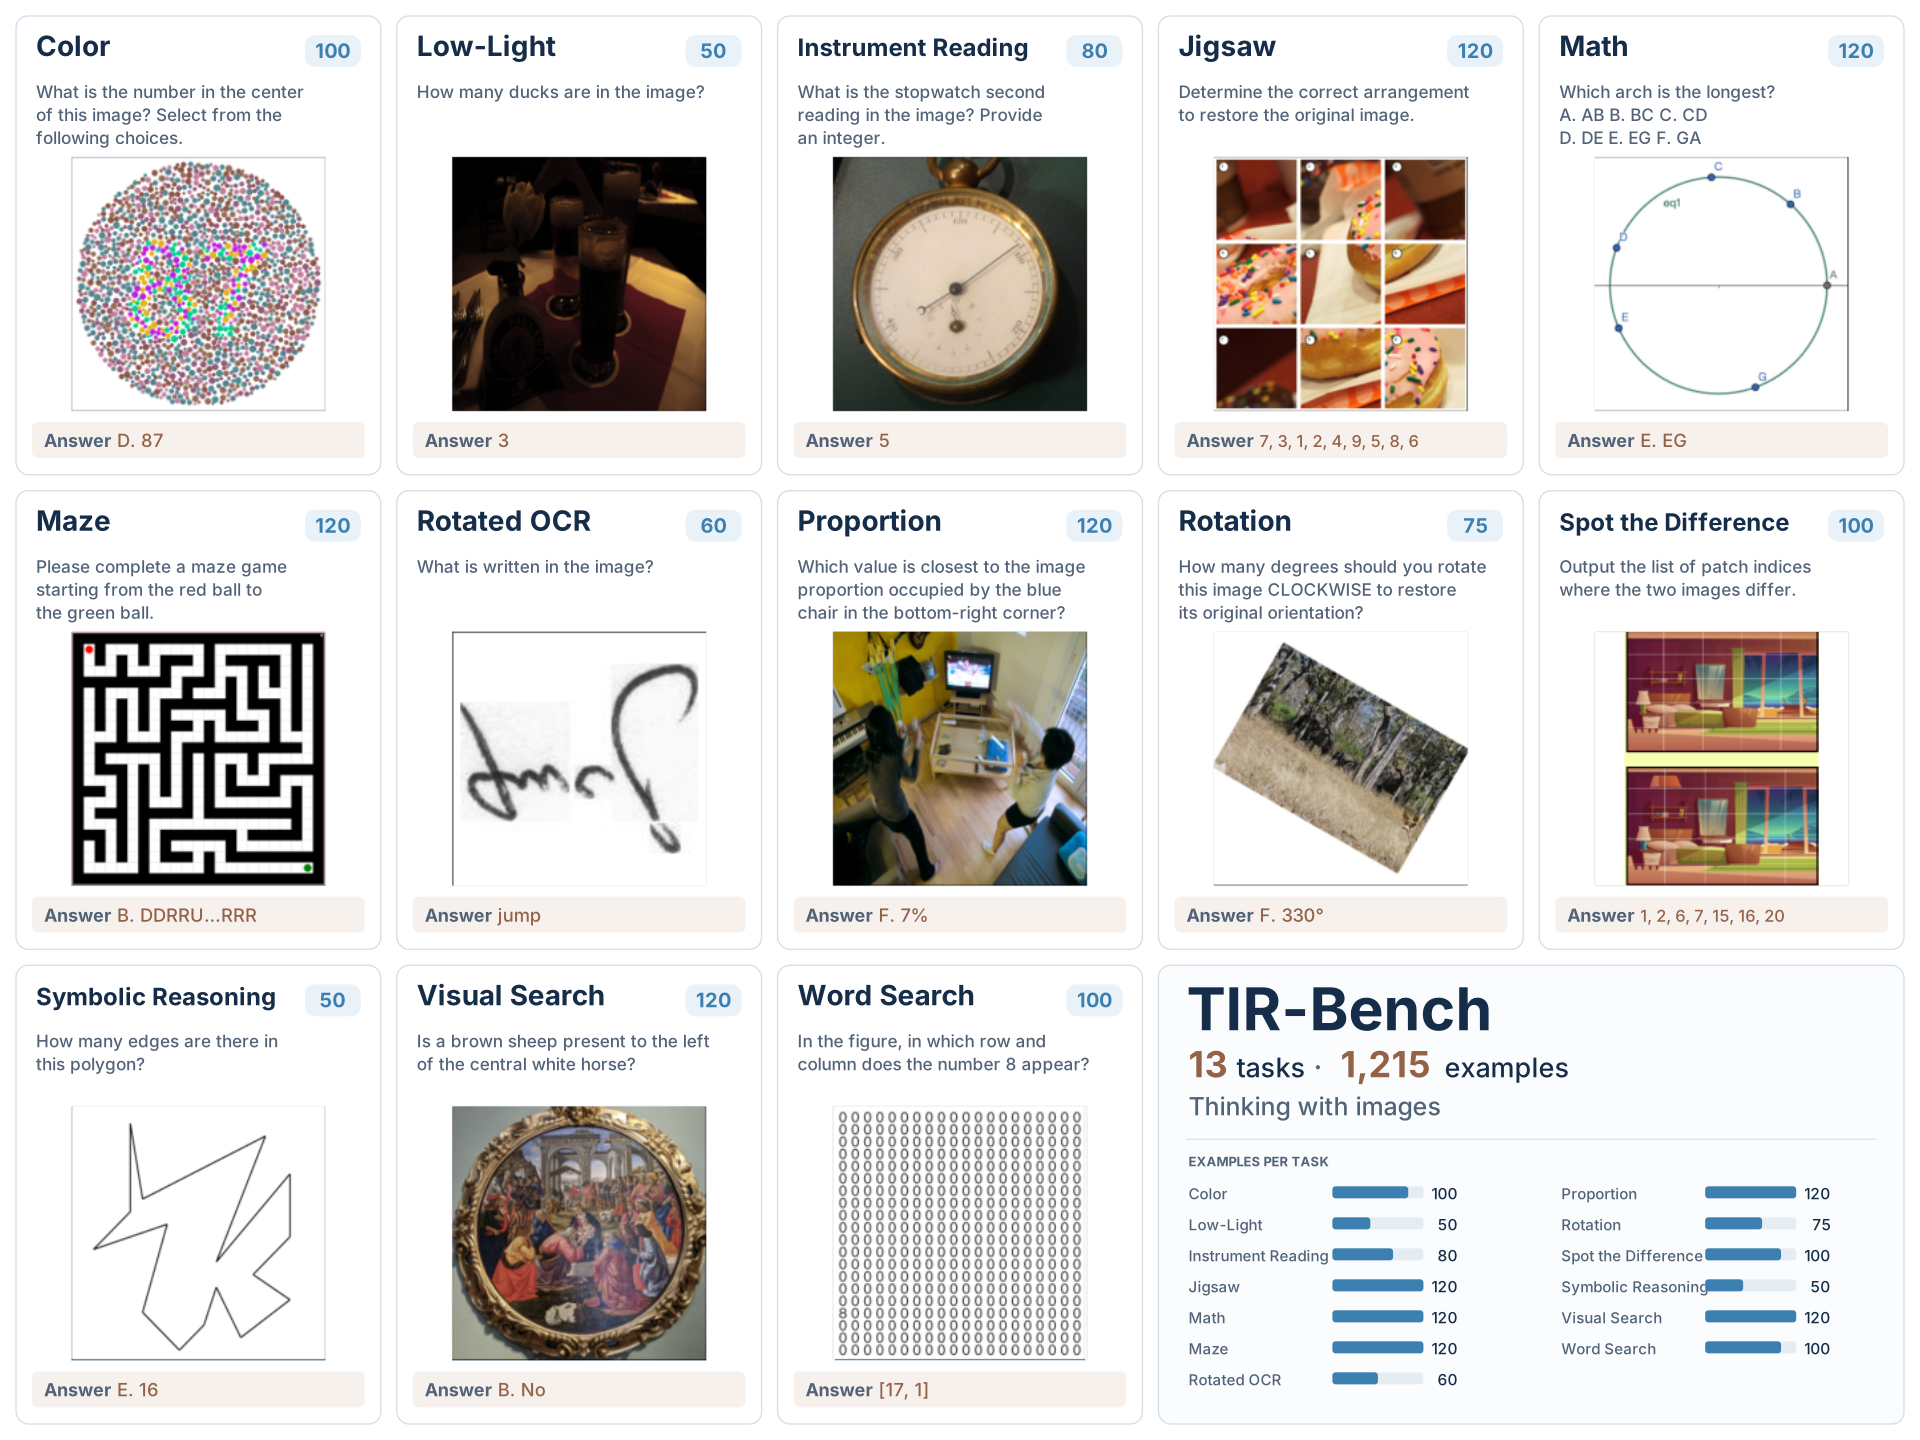
TIR-Bench's 13 visual reasoning tasks, including mazes, jigsaws, rotated text, visual search, and instrument reading.

Agentic AI | Thinking-With-Image | VLM Reasoning | EvaluationTIR-Bench: A Comprehensive Benchmark for Agentic Thinking-with-Images Reasoning

Ming Li*, Jike Zhong*, Shitian Zhao, Haoquan Zhang, Shaoheng Lin, Yuxiang Lai, Chen Wei, Konstantinos Psounis, Kaipeng Zhang

ECCV 2026

We evaluate agents that use tools and code to manipulate visual evidence across 13 tasks and 1,215 examples. Testing 22 multimodal models reveals substantial gaps in agentic visual reasoning; TIR-Bench also informs Qwen3.5 and Qwen3.6 evaluations.

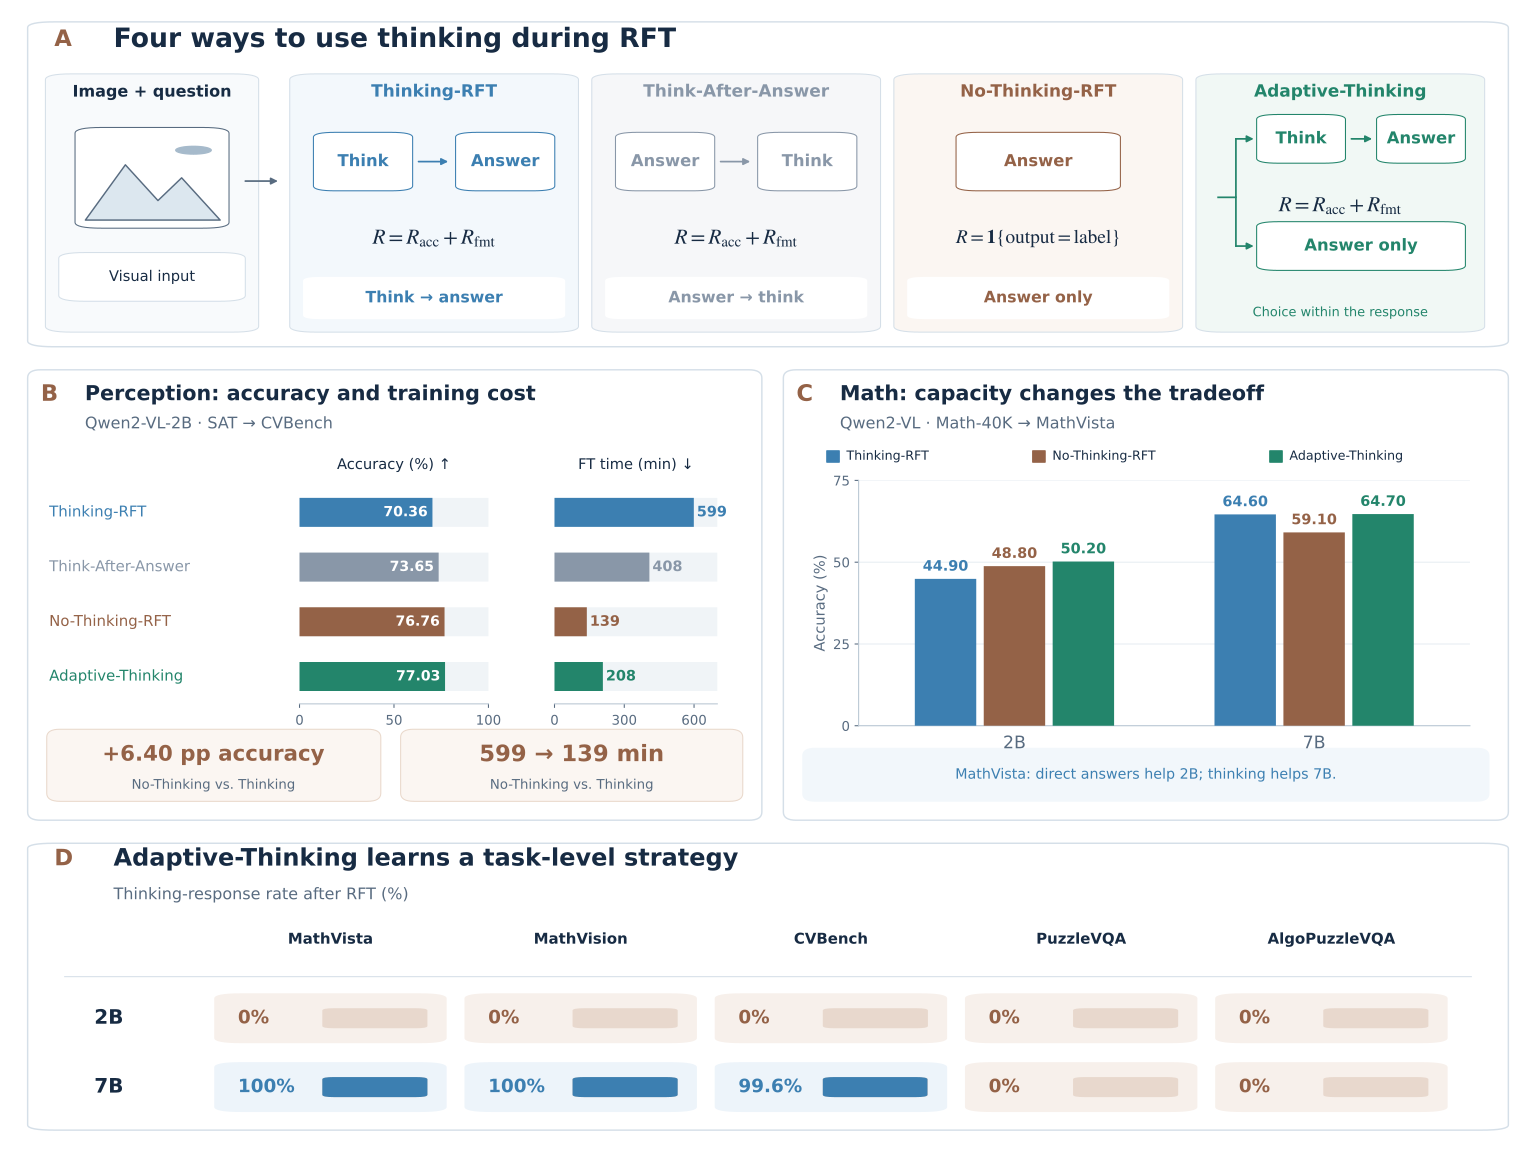
Four visual reinforcement fine-tuning strategies, CVBench accuracy and training time, MathVista results for 2B and 7B models, and the task-level strategies learned by Adaptive-Thinking.

Post-Training | Multimodal RL | Adaptive ThinkingTo Think or Not To Think: A Study of Thinking in Rule-Based Visual Reinforcement Fine-Tuning

Ming Li, Jike Zhong, Shitian Zhao, Yuxiang Lai, Haoquan Zhang, Wang Bill Zhu, Kaipeng Zhang

NeurIPS 2025 · Spotlight

We show that explicit thinking is not always beneficial during visual reinforcement fine-tuning: direct-answer training can match or outperform it on perception tasks while reducing computation. We further explore how models learn whether to think based on their capabilities and task complexity.

Employment

Amazon AGI

May 2026 – Aug 2026 · Bellevue, WA

Applied Scientist Intern · AGI Foundations Group

Foundation-model post-training and stateful memory for long-horizon multimodal agents.

Honda Research Institute USA

May 2025 – Aug 2025 · San Jose, CA

Research Intern · Cognition Group

Robust LLM/MLLM post-training for theory-of-mind reasoning.

Salesforce

May 2023 – Aug 2024 · Bellevue, WA

Member of Technical Staff · Infra Data Science Group

Salesforce

May 2022 – Aug 2022 · San Francisco, CA

Software Engineer Intern

Salesforce

May 2021 – Aug 2021 · San Francisco, CA

Software Engineer Intern

Misc

I’m a big aviation fan. Check out my photographs below or on JetPhotos and Airliners.

I also enjoy classical piano and opera, especially those by Franz Liszt (Hungarian Rhapsody) and Bellini (I Puritani), though the one I play most often currently is Ballade No. 1.

Figure preview

Open original ↗